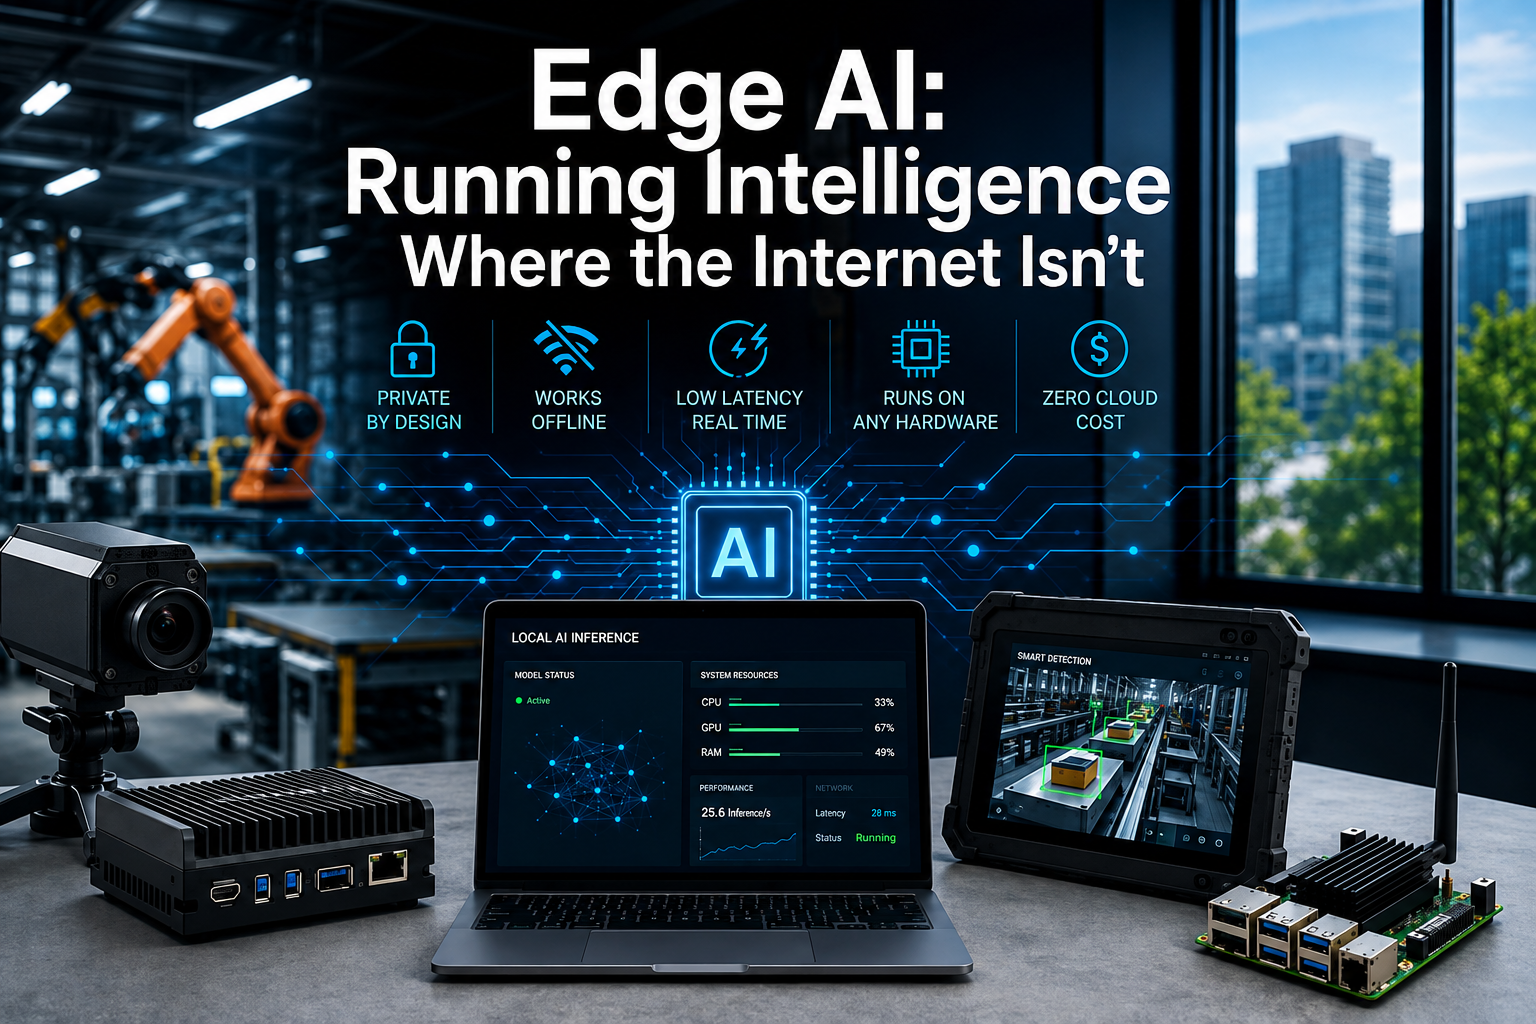
Most AI systems today depend on the cloud. A request travels to a remote server, a large model processes it and the answer travels back. This works until it doesn’t, when connectivity is unreliable, when data is too sensitive to leave the premises or when per request pricing makes continuous usage impractical. Edge AI takes the opposite approach by running models entirely on local hardware, from office laptops to industrial single-board computers. With modern runtimes and efficient model formats, capabilities that required a datacenter three years ago now run on machines organizations already own. Edge AI Is Not Cloud AI Made Smaller The most common mistake teams make is treating edge deployment as a compression problem: take the cloud architecture, shrink the model, ship it. It does not work that way, because the constraint changes the architecture itself. In the cloud, compute is elastic. If inference is slow, you scale up. The design question is simply which model is best. At the edge, hardware is fixed and unknown in advance. The same software may land on a machine with a powerful discrete GPU, one with only integrated graphics or an older CPU with no usable acceleration at all. The design question inverts completely: what is the best system that degrades gracefully across hardware you cannot predict? That inversion shapes everything. Instead of one model, you ship a ladder of models and quantization levels, with runtime logic that selects the right configuration for the machine it wakes up on. Instead of assuming GPU memory, you build a resource arbiter that decides which model gets the GPU when several features want it at once and which fall back to CPU. And because deployed machines may never phone home, the software has to be right before it leaves. The Runtime Layer: Where Optimism Meets Reality Take any model that runs beautifully on a development machine and try it on five random office laptops. What you discover is that “runs locally” is not one capability but a matrix of hardware and runtime combinations, each with its own behavior. ONNX Runtime is the workhorse for encoder-style models such as translation, embeddings, and classification. It offers the strongest cross-vendor GPU support on Windows through DirectML, along with a dependable CPU fallback. llama.cpp handles generative language models. Its Vulkan backend covers an impressive range of consumer GPUs and the GGUF format has become the most practical way to distribute quantized models. NCNN targets vision models on ARM-class hardware, where the deployment target is often a compact single-board computer wired to a camera. Hybrid laptops deserve special mention: machines with both integrated and discrete GPUs frequently default to the wrong device, leaving the powerful GPU idle while the integrated one struggles. Explicit device selection logic is not optional. None of this appears in model release announcements, yet all of it determines whether a system works in the field. Quantization Is a Negotiation, Not a Checkbox Quantization is usually presented as a solved problem: use 4-bit, it is basically lossless. It is not lossless. It is a negotiation and the terms depend on the task. For conversational use, aggressive quantization holds up remarkably well. For structured work such as extracting fields from documents, generating valid JSON, or translating with precise terminology, the cracks appear exactly where they hurt most. A quantized model does not fail loudly. It fails plausibly: a number slightly wrong, a field confidently mislabeled, output that reads fluently but drifted from the source. The discipline that pays off is verifying every quantized build against a full-precision reference on the actual production task, output by output, before it ships. Sometimes the results are identical. Sometimes they are not and you climb back up one quantization level. Good enough at the edge is a measured claim about a specific task on specific hardware, never a feeling. Privacy by Architecture, Not by Policy Every cloud vendor has a privacy page, and what it says in careful language is: trust us. Edge AI replaces that promise with a physical property. Data that never leaves the device cannot leak from a server. There is no retention policy to audit, no subprocessor list to review and no terms-of-service update that quietly changes what happens to your files. For legal teams whose documents contain live case strategy, manufacturers whose cameras capture proprietary processes, healthcare providers handling patient records, and enterprises facing tightening data residency requirements, this distinction often decides whether an AI deployment is possible at all. Procedural privacy asks you to trust an organization. Structural privacy asks you to trust an air gap. One of those is a much shorter conversation. Manufacturing in Practice Two examples from our own work show what this looks like on an actual shop floor. A manufacturing client needed to confirm workers were wearing required safety gear, without routing camera feeds through the cloud. We trained a YOLO11n detector, exported it through ONNX to NCNN and ran it directly on ARM-class hardware sitting next to the existing cameras. No footage leaves the plant, there’s no per-camera cloud bill, and the model keeps working even when the plant’s internet connection doesn’t. Manufacturing defect data has an awkward property: you have thousands of images of good parts and almost none of bad ones, because defective parts get pulled before anyone photographs them. For a fastener inspection use case, we used an anomaly detection model that trains on normal parts alone and flags anything that deviates, exported to ONNX and deployed on a Raspberry Pi. Detected anomalies get pushed to the factory’s existing systems over MQTT, so the model plugs into infrastructure that’s already there instead of requiring a new dashboard nobody opens. Both systems share the same shape as everything else in this piece: hardware-adaptive, verified against a reference before deployment and built so the data never has to leave the building. Small Models Doing Real Work The most counterintuitive lesson from running language models locally: raw model intelligence is overrated for a large class of practical workloads.