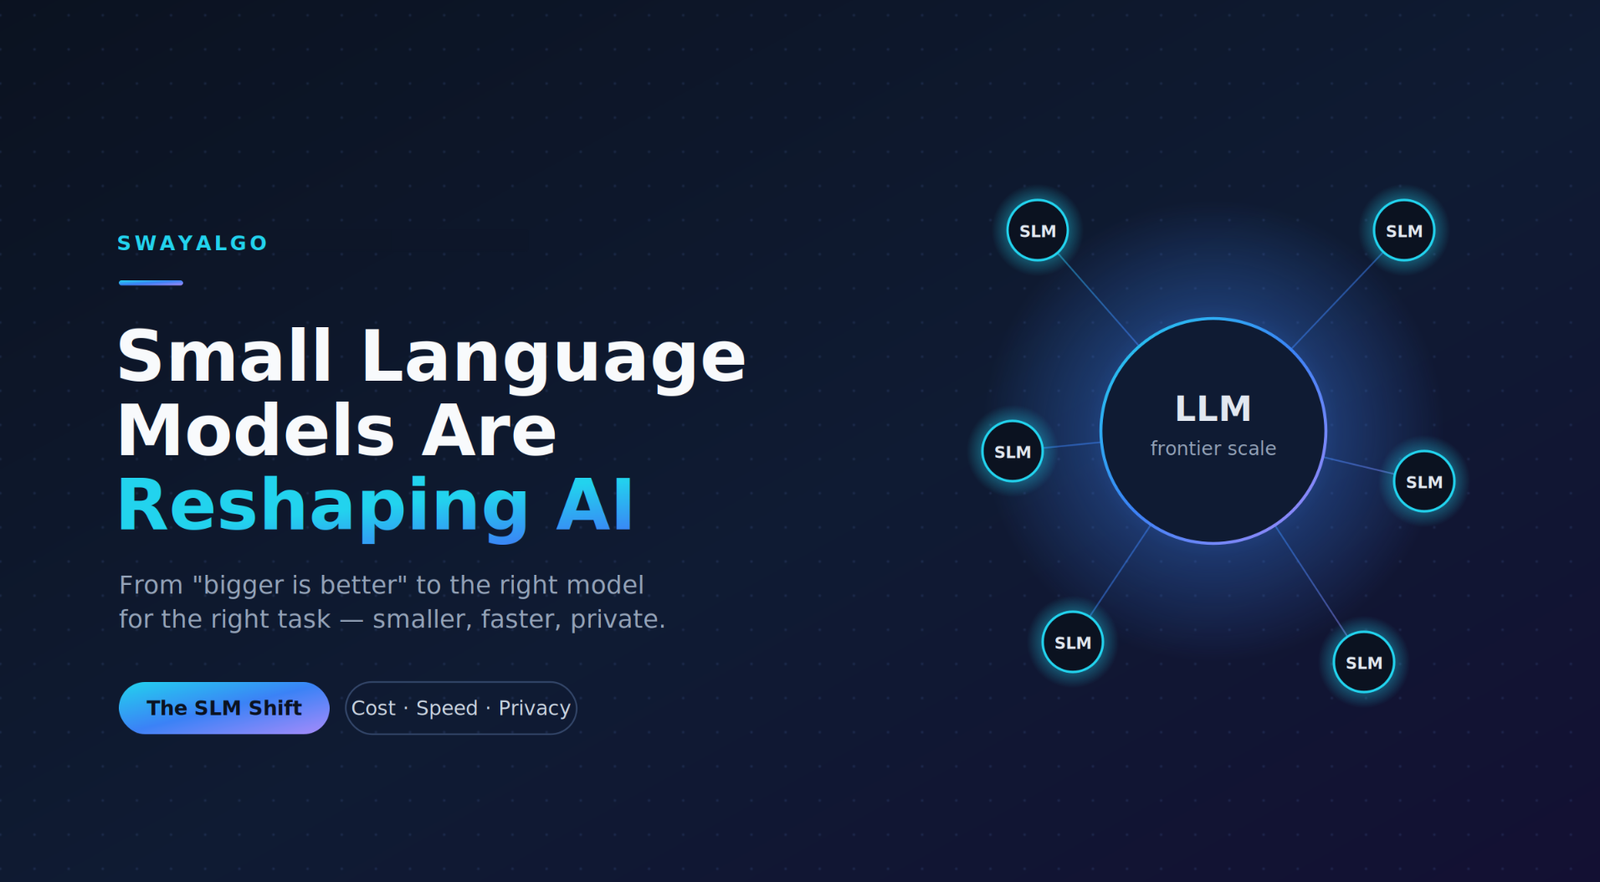
For the past few years, progress in artificial intelligence has been measured by a single question: Whose model is bigger? Each new generation of Large Language Models (LLMs) arrived with more parameters, larger training budgets, and broader general capabilities. But as organizations move from AI experimentation to real-world production systems, a quieter shift is taking place—one that trades raw scale for precision, efficiency and control. At SwayAlgo Technologies, we see this shift clearly in the field. Enterprises are no longer asking only, “Which model is the most powerful?” They are increasingly asking: “Which model is the fastest, cheapest, most private and best suited to my specific task?” Increasingly, the answer is a Small Language Model (SLM). Small Language Models are compact, efficient models—typically ranging from a few hundred million to around ten billion parameters—engineered to run on limited hardware while delivering strong performance on focused tasks. They sacrifice some general breadth compared to frontier LLMs, but they can deliver significant advantages in speed, cost, privacy and deployability. This is not a rejection of LLMs. It represents a maturing of how the industry approaches AI. Rethinking “Bigger vs Smarter” The “bigger is better” philosophy delivered remarkable breakthroughs, but it also introduced significant operational challenges for businesses. Running a large, general-purpose model for every task means paying a computational cost for work that a smaller, specialized model could often handle efficiently. A significant share of enterprise AI workloads involve narrow, repetitive tasks such as: Classification Data extraction Routing Summarization Information transformation Structured response generation For these workloads, a tuned SLM can deliver faster responses at a fraction of the cost. The industry is therefore moving from: “Which model has the most parameters?” to: “Which model is best suited to this specific task?” This leads to several practical questions: Which model matches the specific workload? What are the actual cost and latency requirements? Where does the data need to reside? How much general-purpose knowledge does the workload actually require? Can the task be handled locally or on-premises? This reframing is at the heart of the SLM movement. Success in AI is increasingly measured not by which model you use, but by how effectively you match models to tasks. The Economics of Going Small Cost is often the first factor that pushes organizations toward SLMs. At scale, cloud API pricing for very large models can add up quickly. Heavy usage can result in significant and sometimes unpredictable monthly expenses. Smaller models can fundamentally change this equation. Key Economic Advantages Lower inference and GPU costs Near-zero variable inference costs when deployed on owned infrastructure Faster and less expensive fine-tuning cycles Reduced energy consumption and infrastructure requirements Lower barriers to AI adoption for SMEs and smaller teams Serving a compact model can be significantly cheaper than running a frontier-scale model for the same high-volume workload. For repetitive enterprise tasks, this cost difference can determine whether an AI feature is economically viable. Privacy, Data Sovereignty and Compliance For regulated industries, cost is only part of the equation. Control over data is often the deciding factor. Sending sensitive information to a third-party cloud model may not be acceptable for organizations operating in sectors such as: Healthcare Banking and financial services Legal services Government Defense Manufacturing SLMs can be deployed on-premises, within private clouds or directly on edge devices, allowing organizations to keep sensitive data within their own infrastructure boundaries. This Enables: On-device and on-premises inference Reduced exposure to third-party and multi-tenant risks Improved control over data residency Greater auditability and governance Stronger control over AI workloads and data flows For enterprises that cannot afford data leakage, a capable model that they fully control can be more valuable than a slightly more capable model that requires external infrastructure. Speed, Latency and On-Device Intelligence Many real-world applications are interactive and users notice latency immediately. Cloud round-trips to very large models can introduce delays that negatively affect real-time experiences. Smaller models running closer to the user—on a laptop, smartphone, server or edge device—can dramatically reduce this latency. Modern hardware is accelerating this trend. Why On-Device AI Is Becoming Practical Neural Processing Units (NPUs) are increasingly available in laptops and smartphones More devices can run capable local AI models Edge deployment reduces dependence on continuous connectivity Lower latency enables responsive real-time applications Local execution allows applications to continue functioning offline Sensitive information can remain on the device On-device AI is no longer purely experimental. It is becoming an increasingly important layer of modern software, and SLMs are helping make that transition practical. Domain Specialization Beats General Breadth A large model can know something about almost everything. But most business applications do not need a model that knows everything. They need a model that knows a lot about one specific thing. This is where SLMs can shine. When fine-tuned or adapted using focused, domain-specific data, a smaller model can perform extremely well on the task it was designed for. Common SLM Applications Document processing and structured data extraction Ticket classification and intelligent routing Contract and clause identification Transaction analysis and fraud detection Clinical documentation and record population Customer support for specialized domains Enterprise workflow classification Internal knowledge and process assistants By narrowing the scope, organizations can gain accuracy, consistency, predictability and efficiency without paying the operational cost of a much larger general-purpose model. SLMs and the Rise of Agentic AI Autonomous AI agents are changing how software gets work done—and they are also changing how organizations should think about model selection. Agentic systems often break complex objectives into many smaller steps, such as: Understanding the next action Selecting the appropriate tool Formatting a request Calling an API Parsing a response Validating the result Retrying when necessary Passing the output to the next step Not every step requires frontier-scale reasoning. Many require fast, reliable, predictable and low-cost execution—exactly where SLMs can provide value. An SLM-First Agentic Architecture Can Enable: Lower-cost execution of high-frequency agent steps Faster tool calling and workflow orchestration More predictable behavior within defined boundaries Lower operational overhead for always-on agents